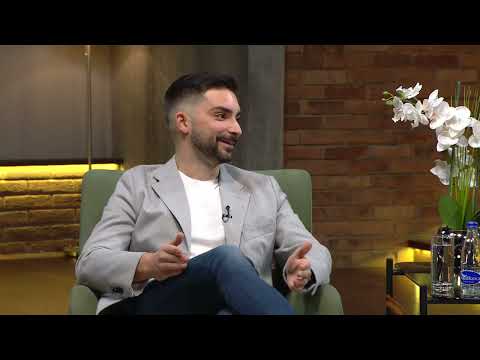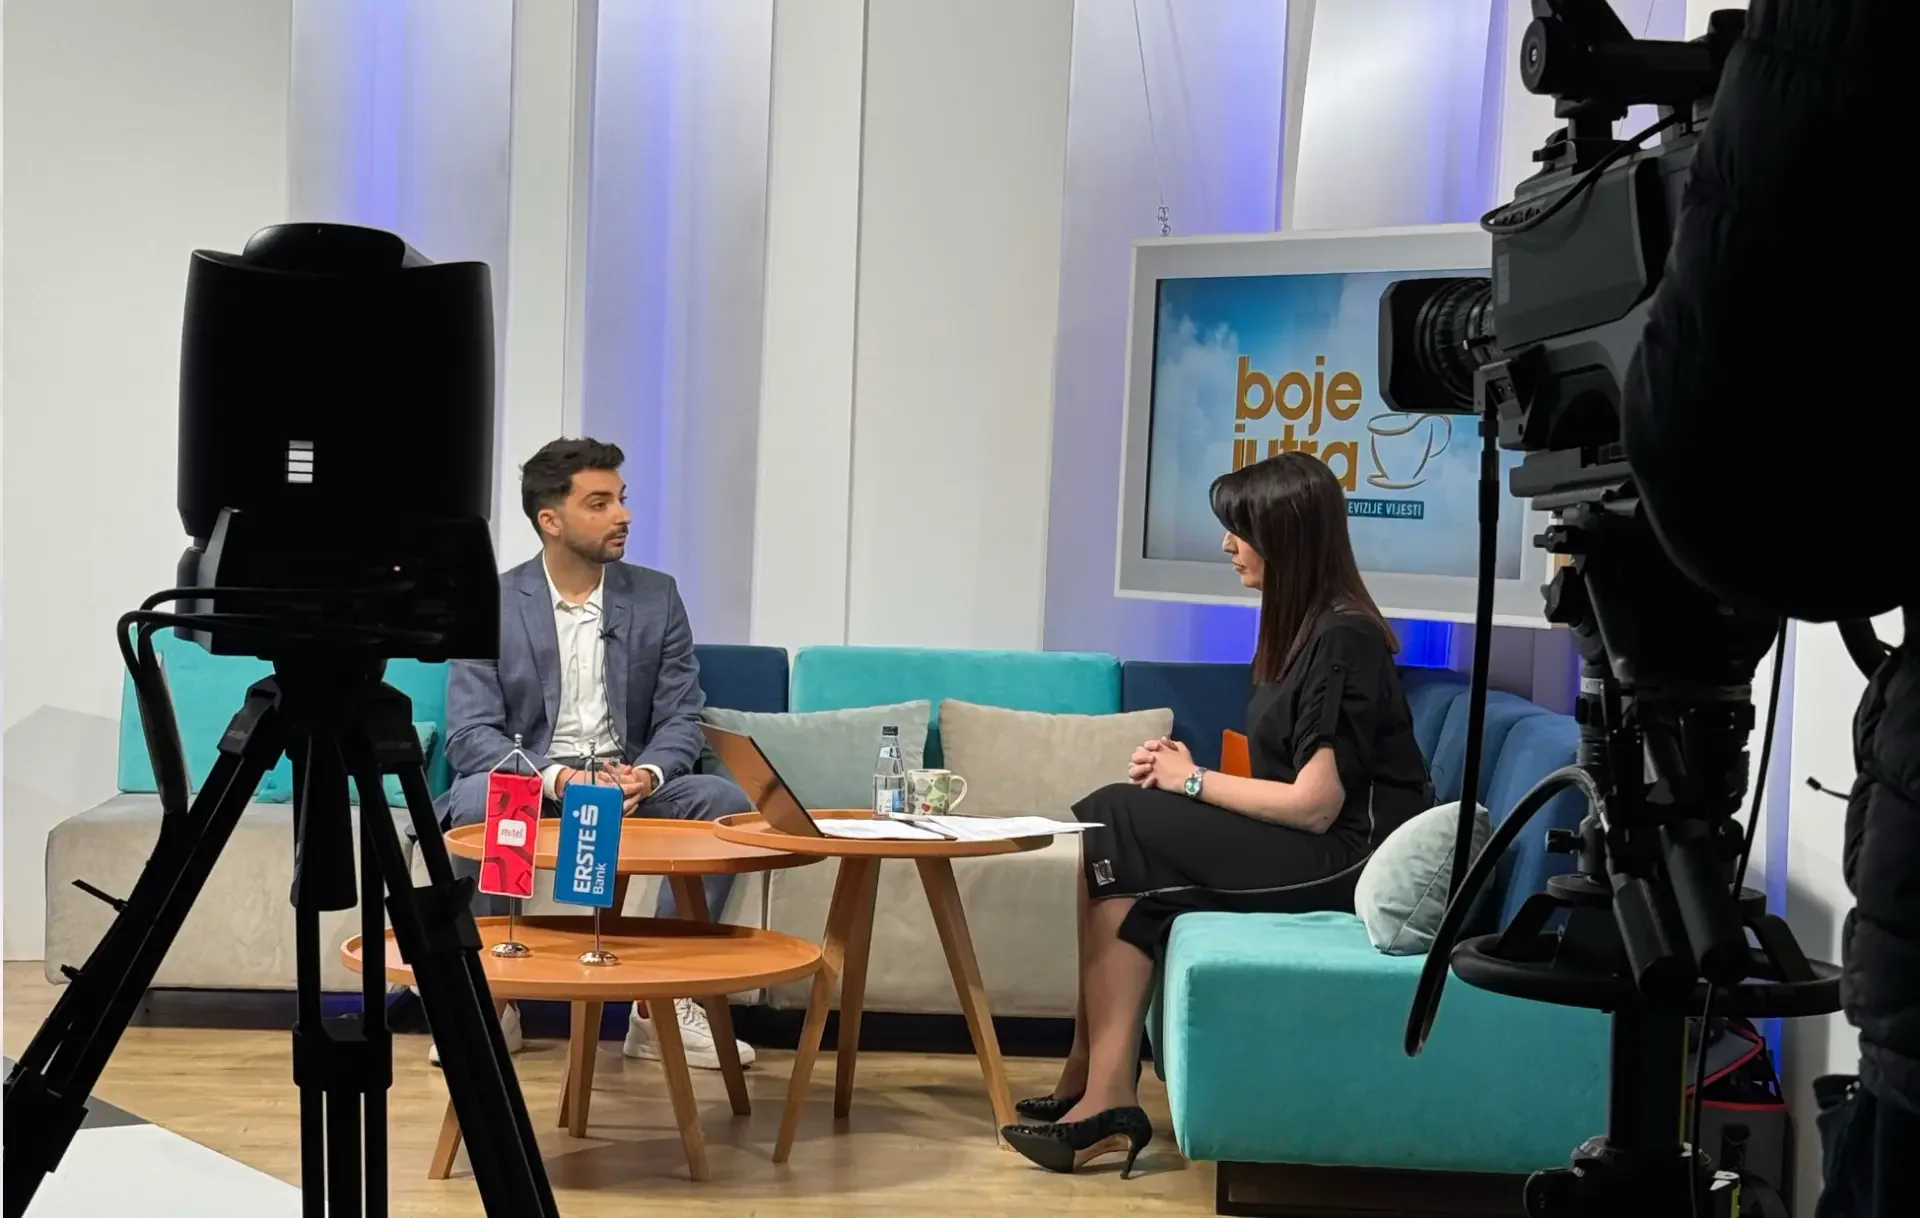
On 19 July 2024, the day of the global IT outage, I joined the N1 programme Dan uživo as a cybersecurity expert at BrightMarbles Group. We talked about the causes, the risk of cyberattacks that such moments bring, and how companies can keep something similar from stopping them.

Dan uživo, TV N1
What happened
The crash was caused by two problems that hit Microsoft systems within a short time.
The first came the day before, when Azure, the cloud service of Microsoft, failed in the central United States. That hit a large number of airlines, banks, airports and financial institutions, and even government institutions. According to the information available at the time, the suspected cause was a misconfiguration in part of the services, which then affected other Microsoft services in a chain.
The second came on the day itself, when many Windows devices crashed with the blue screen of death, which brings down the whole operating system. The cause was a faulty security update to Falcon Sensor, the endpoint protection software of the cybersecurity company CrowdStrike.
A golden moment for attackers
A situation like this can open the door to cyberattacks. When a security service goes down or struggles to function, protection is weaker, and criminals step up their activity. They try to steal data and money or disable systems while defenders are busy with recovery. I said on air that I expected reports of increased attack activity worldwide in the following days.
Two recommendations you can apply today
Both are common practice in cybersecurity.
- Manage software updates proactively. Test new software versions before you roll them out across the company. That means a test environment where you assess problems before an update reaches production systems and every employee computer.
- Keep a crisis plan. Develop and regularly update business continuity and crisis management plans. Include clear steps for a quick response and for restoring systems, and alternative ways of providing your service, all the way back to paper and pencil.
What a small company can take from it
You probably cannot run a full test environment for every tool. You can still do three things.
- Roll updates out to a few computers first and to everyone a day later, where the tool allows it.
- Write down how you would serve customers for one day without your main systems, and keep a printed copy.
- List the suppliers whose failure would stop your business, including your security tools, and record them in your risk register.
The outage was a mistake and not an attack. The lesson is the same in both cases, because your customers experience a stopped business the same way.
Where this first appeared
InterviewTV N119 Jul 2024
Watch the live interview on N1 (in Serbian)Write-updzakula.com19 Jul 2024
Read the write-up on dzakula.com
See what your company has left exposed.
Request a trial